
How should researchers applying machine learning to quantitative finance address the field’s data limitations, which exacerbate data snooping bias? In their October 2018 paper entitled “A Backtesting Protocol in the Era of Machine Learning”, Robert Arnott, Campbell Harvey and Harry Markowitz take a step back and re-examine financial markets research methods, with focus on suppressing backtest overfitting of investment strategies. They introduce a research protocol recognizing that self-deception is easy. Their goal is that the protocol offers the best way to match or beat expectations in live trading. Based on logic and their collective experience, they conclude that:
- 55 years of broad, high-quality firm/stock data are available. This sample is tiny for most machine learning applications, and impossibly small for advanced methods such as deep learning.
- In this environment, with intensive backtesting, false strategies can survive simple cross-validation (such as a single validation test).
- When data are so limited, economic foundations are critical.
- The proposed research protocol has seven elements:
- Carefully guide machine learning tests by a prior reasonable hypothesis. Any hint that review of data preceded hypothesis development is a red flag.
- Keep track of everything tried, including combinations of variables, as a source of data snooping bias. Understand the secondary bias derived from the entire community of researchers working on similar backtests.
- Specify and clean the training sample in advance, before examining the data. Acknowledge that transformations such as winsorizing/exclusion of outliers and volatility scaling amount to introducing additional variables.
- Understand that researcher experience contaminates any hold-out sample during which the researcher lived, such that true historical out-of-sample data hardly exist. The only truly fresh samples are live trading data. Iterated out-of-sample testing of model variations is overfitting, not out-of-sample testing. All research must account for contemporaneous trading frictions and implementation barriers.
- Understand that studying and refining a model generally increases the mismatch between expectations and true performance. While modifications are a natural response to failure, they generally increase overfitting and may worsen live trading performance.
- Investment managers should not accept machine learning as a black box. The greater the complexity of a model and the greater the reliance on non-intuitive relationships, the greater the mismatch between backtest and live results.
- Organizations/customers should reward researchers for good science, not good backtest results, with the expectation that most tests will fail. Incentivizing good backtests encourages data snooping.
The following protocol summary, extracted from the paper, alternatively summarizes the seven elements.
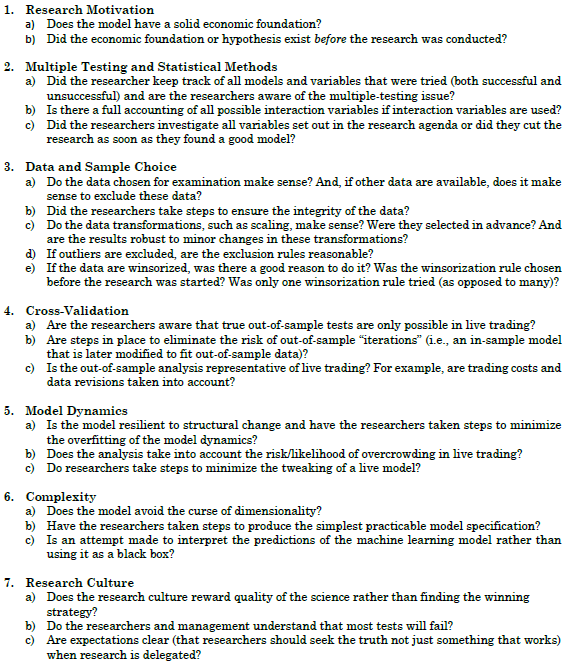
In summary, the proposed financial markets research protocol balances dual objectives of suppressing false strategies while discovering good ones.
Cautions regarding conclusions include:
- Conventional incentives work against adoption of the proposed research protocol.
- Research on contemporaneous trading frictions and implementation barriers (such as shorting constraints) is thin. These costs/barriers vary considerably across types of investors.
- Costs should also include those for initial research and for recurring research/analyses to support implementation.
Frequently Asked Questions
What is backtest overfitting in quantitative investing?
Backtest overfitting occurs when an investment strategy is tuned, through repeated testing and refinement on historical data, to look good in the backtest but not in live trading. Arnott, Harvey and Markowitz (October 2018) tie it to data snooping bias, which is worsened by the roughly 55 years of broad, high-quality firm/stock data available. Because false strategies can survive simple cross-validation in such a small sample, backtest results tend to overstate live performance.
Does machine learning work reliably for finding investment strategies with limited historical data?
Machine learning is unreliable for finding investment strategies when data are limited, according to Arnott, Harvey and Markowitz. About 55 years of broad, high-quality stock data is a tiny sample for most machine learning applications and impossibly small for methods such as deep learning. With intensive backtesting, false strategies can pass simple cross-validation, so economic foundations and prior hypotheses are critical.
How does a research protocol reduce data snooping in machine learning backtests?
The Arnott-Harvey-Markowitz protocol reduces data snooping through seven elements, including guiding tests with a prior reasonable hypothesis, tracking everything tried, and specifying and cleaning the training sample before examining the data. It also treats outlier winsorizing and volatility scaling as additional variables, accounts for trading frictions, and rejects iterated out-of-sample testing of model variations as overfitting. It further advises against treating machine learning as a black box and urges rewarding researchers for good science rather than good backtest results, expecting most tests to fail.
Is historical out-of-sample testing the same as testing a strategy on live trading data?
Historical out-of-sample testing is not the same as live trading data, according to Arnott, Harvey and Markowitz. Researcher experience contaminates any hold-out sample from a period the researcher lived through, so true historical out-of-sample data hardly exist. The only truly fresh samples are live trading data, and iterating out-of-sample tests across model variations is overfitting rather than genuine out-of-sample testing.
What are the limitations of using a backtesting protocol to prevent overfitting?
The proposed backtesting protocol faces the caveat that conventional incentives work against its adoption. Research on contemporaneous trading frictions and implementation barriers, such as shorting constraints, is thin, and these costs vary considerably across types of investors. Costs should also include those for initial research and for recurring research and analyses to support implementation.