
Iterative testing of strategies on a set of data introduces snooping bias, such that a winning (losing) strategy is to some degree lucky (unlucky). Sharing of strategies across a community of researchers carries the luck forward, with accretion of additional bias from testing by subsequent researchers. Is there a rigorous way to account for this accumulation of snooping bias? In the October 2013 version of their paper entitled “Backtesting”, Campbell Harvey and Yan Liu describe three types of adjustment for snooping bias and apply them to quantify the snooping bias “haircut” appropriate for any reported Sharpe ratio (in lieu of a 50% rule-of-thumb discount). Using mathematical derivations and examples, they conclude that:
- Across a range of number of test iterations, all three types of snooping bias adjustment penalize marginal strategies heavily because they are likely false discoveries. Specifically (see the chart below), when a strategy’s annualized gross Sharpe ratio is:
- Less than 0.4, the snooping bias haircut is almost always above and sometimes far above 50%.
- Greater than 1.0, the snooping bias haircut is at most 25%.
- Results indicate that a 50% rule-of-thumb Sharpe ratio discount is inappropriately lenient (harsh) for strategies with relatively small (large) estimated gross Sharpe ratios.
The following chart, taken from the paper, illustrates the gross annualized Sharpe ratio snooping bias haircuts (discounts) for 100 test iterations as generated by the three types of adjustment considered, designated by the names of their respective developers: Bonferroni; Holm; and, Benjamini, Hochberg and Yekutieli (BHY). For all three adjustment approaches, haircuts applied to strategies with low estimated Sharpe ratios are percentage-wise much larger than those applied to strategies with very high estimated Sharpe ratios.
The authors advocate the BHY method, unless there is some severe consequence of a false discovery.
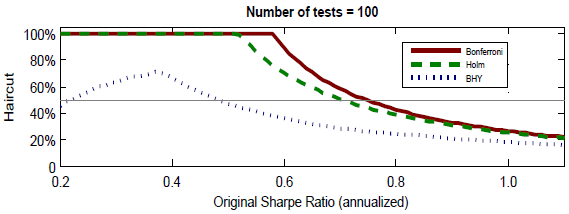
In summary, analysis suggests that investors should discount estimated Sharpe ratios of strategies they develop by a lot (little) if the estimated Sharpe ratios are marginally (highly) attractive.
Cautions regarding the proposed approach are:
- As noted by the authors:
- Conventional interpretation of the Sharpe ratio assumes a normal return distribution.
- The most appropriate type of data snooping adjustment and the underlying required confidence level in the Sharpe ratio may vary by investor.
- Without precise tracking of the number of strategies considered, the estimated number of test iterations requires judgment.
- It is arguably impossible to estimate the number of strategy iterations tested and shared across the investing community.
- The mathematics may be daunting for some investors.
The authors provide a program for others to try.
For related research, see “Measuring Investment Strategy Snooping Bias”, “Insidiousness of Overfitting Investment Strategies via Iterative Backtests” and “Taming the Factor Zoo?”.
Frequently Asked Questions
What is data snooping bias in investment strategy backtesting?
Data snooping bias is the distortion that arises when strategies are tested iteratively on the same data, so a winning strategy is to some degree lucky (and a losing one unlucky). Sharing strategies across a community of researchers carries this luck forward and adds further bias as subsequent researchers test them. Harvey and Liu quantify the effect as a 'haircut' applied to a reported Sharpe ratio.
How large a Sharpe ratio haircut should investors apply to a backtested strategy to account for data snooping?
The appropriate Sharpe ratio haircut varies with the strategy's performance rather than being a flat 50%. Per Harvey and Liu, when the annualized gross Sharpe ratio is below 0.4, the haircut is almost always above and sometimes far above 50%, while above 1.0 it is at most 25%. A 50% rule of thumb is therefore too lenient for low-Sharpe strategies and too harsh for high-Sharpe strategies.
How do Bonferroni, Holm, and BHY adjustments work to correct for data snooping in Sharpe ratios?
Harvey and Liu apply three multiple-testing adjustments, Bonferroni, Holm, and Benjamini-Hochberg-Yekutieli (BHY), to quantify the haircut appropriate for a reported Sharpe ratio given the number of test iterations. Using mathematical derivations and examples (including 100 test iterations), all three penalize marginal strategies heavily because they are likely false discoveries. The authors advocate BHY unless a false discovery would carry severe consequences.
Is a flat 50% Sharpe ratio discount a good rule of thumb compared with multiple-testing haircuts?
A flat 50% Sharpe ratio discount is not a good substitute for multiple-testing haircuts, because the appropriate discount depends on how high the estimated Sharpe ratio is. Harvey and Liu find the 50% rule is inappropriately lenient for strategies with small estimated gross Sharpe ratios and inappropriately harsh for those with large ones. Under the Bonferroni, Holm, and BHY adjustments, haircuts are percentage-wise much larger for low-Sharpe strategies than for very high-Sharpe ones.
What are the limitations of using Sharpe ratio haircuts to adjust for data snooping?
The Sharpe ratio haircut approach has several caveats noted by the authors. The conventional Sharpe ratio interpretation assumes normally distributed returns, and the best adjustment type and required confidence level may vary by investor. The number of test iterations requires judgment without precise tracking of strategies considered, and it is arguably impossible to estimate the iterations tested and shared across the investing community. The mathematics may also be daunting, though the authors provide a program.